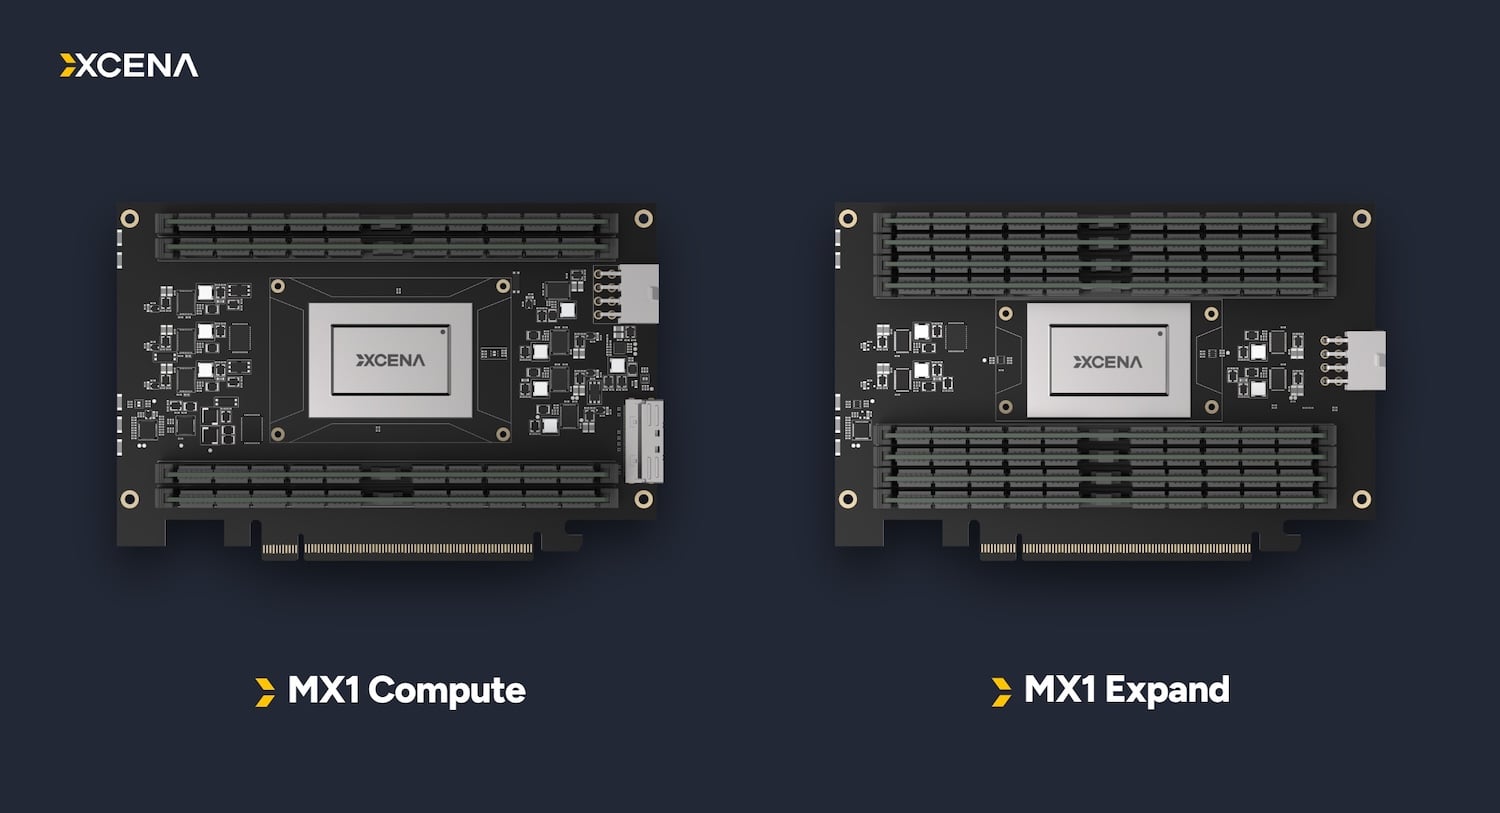
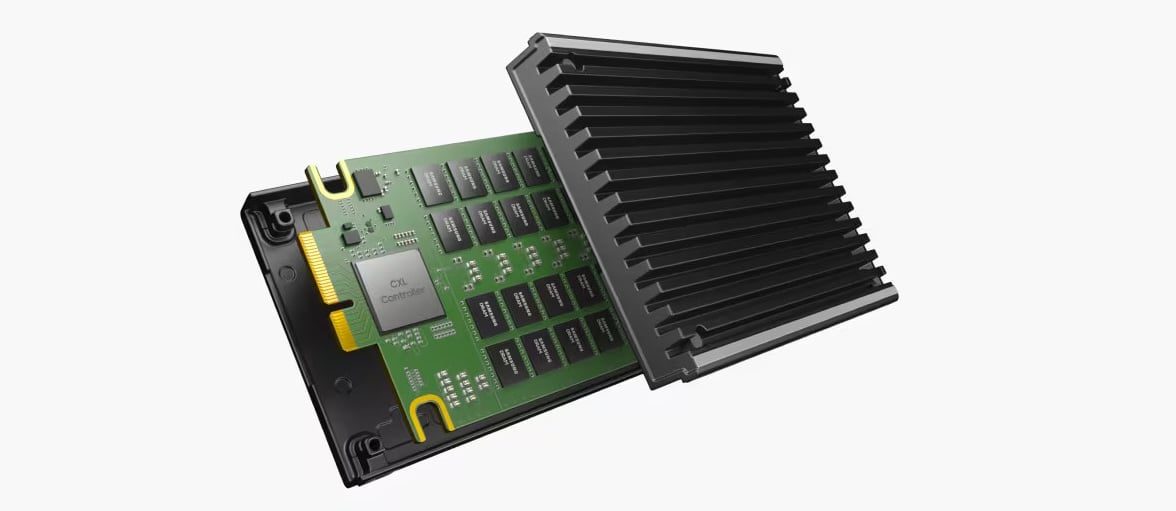
XCENA MX1 CXL Computational Memory Shares a KV Cache Across Inference Servers and Powers SK hynix CXL Hybrid Memory at OCP 2026
XCENA showed two AI inference demonstrations built on its MX1 CXL computational memory at the OCP Global Summit 2026 in San Jose: a KV cache shared across inference servers through a CXL memory pool, and vector search for retrieval-augmented generation (RAG)…
Adjust this page to suit you. Your choices are saved in this browser.
Cookies. Chipokia uses one cookie, and only if you allow it: a random ID so your up and down votes stay yours. No analytics, no advertising, no tracking of any kind. Cookie & Privacy Policy.